
When discussing personal data protection, attention often focuses on technical safeguards such as encryption, access management, and cybersecurity controls. However, a more fundamental step precedes all these measures: determining whether the organization needs to collect the data in the first place.
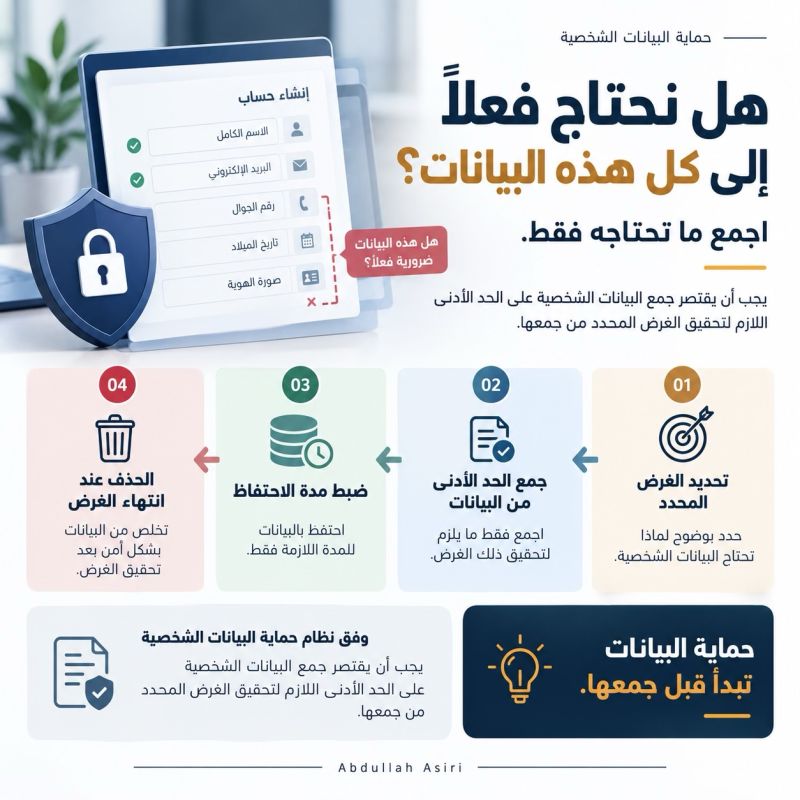
This is where the principle of Data Minimization applies. It requires collecting only the data necessary to achieve a specific and legitimate purpose, instead of gathering as much personal data as possible merely because it might be useful in the future.
This principle directly influences the design of digital services and systems. The key question should not be, “What data can we collect?” but rather, “What data is genuinely necessary and without which the service cannot be delivered?”
Retaining data for which there is no actual need may increase the burden of managing access rights, retention periods, data protection, and the data lifecycle. It may also increase the risks associated with unauthorized exposure or misuse.
This principle becomes even more important with the growing use of artificial intelligence and advanced analytics. The technical ability to collect and analyze large volumes of data does not necessarily mean that collecting such data is required or appropriate.
From this perspective, an organization’s ability to identify the data it does not need to collect can be viewed as an indicator of maturity in data protection and privacy.
Data protection does not begin only after data has been stored in systems. It begins with making the right decision about what should be collected, why it is needed, and how long it should be retained.
To view the original post and learn more on LinkedIn:
https://lnkd.in/p/d-xd-icN
Source: A LinkedIn post by Mr. Abdullah Asiri.